Newscatcher vs NewsData.io, and when to skip both
Pick NewsData.io or Newscatcher if you need a documented news API with its own index and filters. Skip both if you want what Google News ranks, as full-text Markdown with duplicates removed. We ran Newscatcher's self-serve News API (free plan), NewsData.io (free key) and Google News RSS on the same two queries in one 6-minute window on 2026-11-02. Feedmarkdown's numbers are from 2026-11-01. Newscatcher's CatchAll and Agent products and its Enterprise features are out of scope and untested. For the wider field, see Is there a Google News API?.
Update 2026-11-02: the first version of this post had no Newscatcher measurements and quoted its older v3 docs. We replaced those claims with what we measured and what the current docs say, and re-ran NewsData.io and Google News RSS in the same window as Newscatcher.
Short answer on which one to pick
- Newscatcher: ranked results with direct publisher URLs on a free plan, newest item 1.1 h old on one query and 6.4 h on the other, but no article text and noisy relevance in our check.
- NewsData.io: more history and tags by tier, but the free key had a 12-hour delay and no article text.
- Google News plus a pipeline: Google's selection with full text, built yourself or hosted, for example with Feedmarkdown.
What Newscatcher and NewsData.io are
Both crawl the web themselves and sell JSON over REST. Neither is Google News, so results come from the vendor's index, not from what Google ranks.
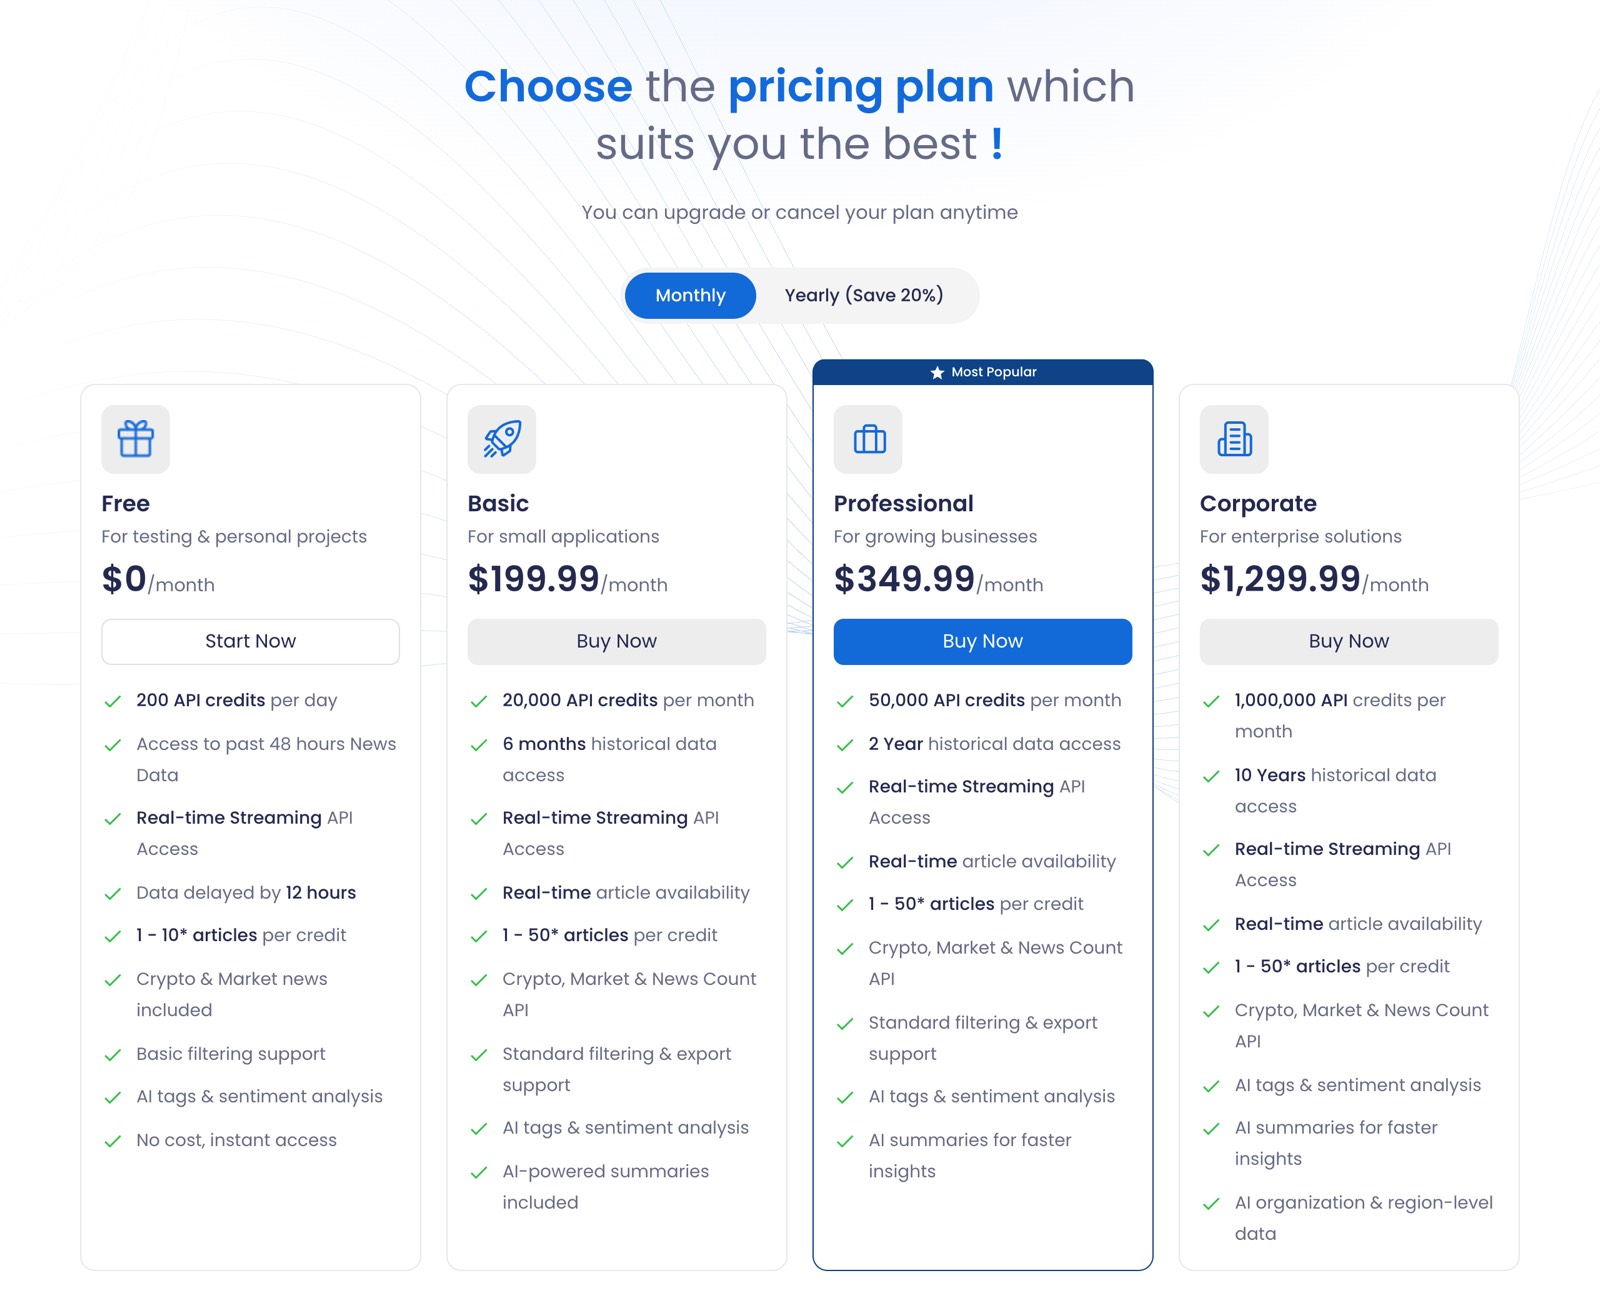
NewsData.io (newsdata.io) has a free plan and four paid tiers. Its docs claim "102434+ trusted news publishers" (vendor states, read 2026-11-01).
Newscatcher (newscatcherapi.com) sells a Web Search API (CatchAll) and a News API. We compare the News API only. Its pricing page says "Structured news from 140k+ sources" (vendor states, read 2026-11-02).
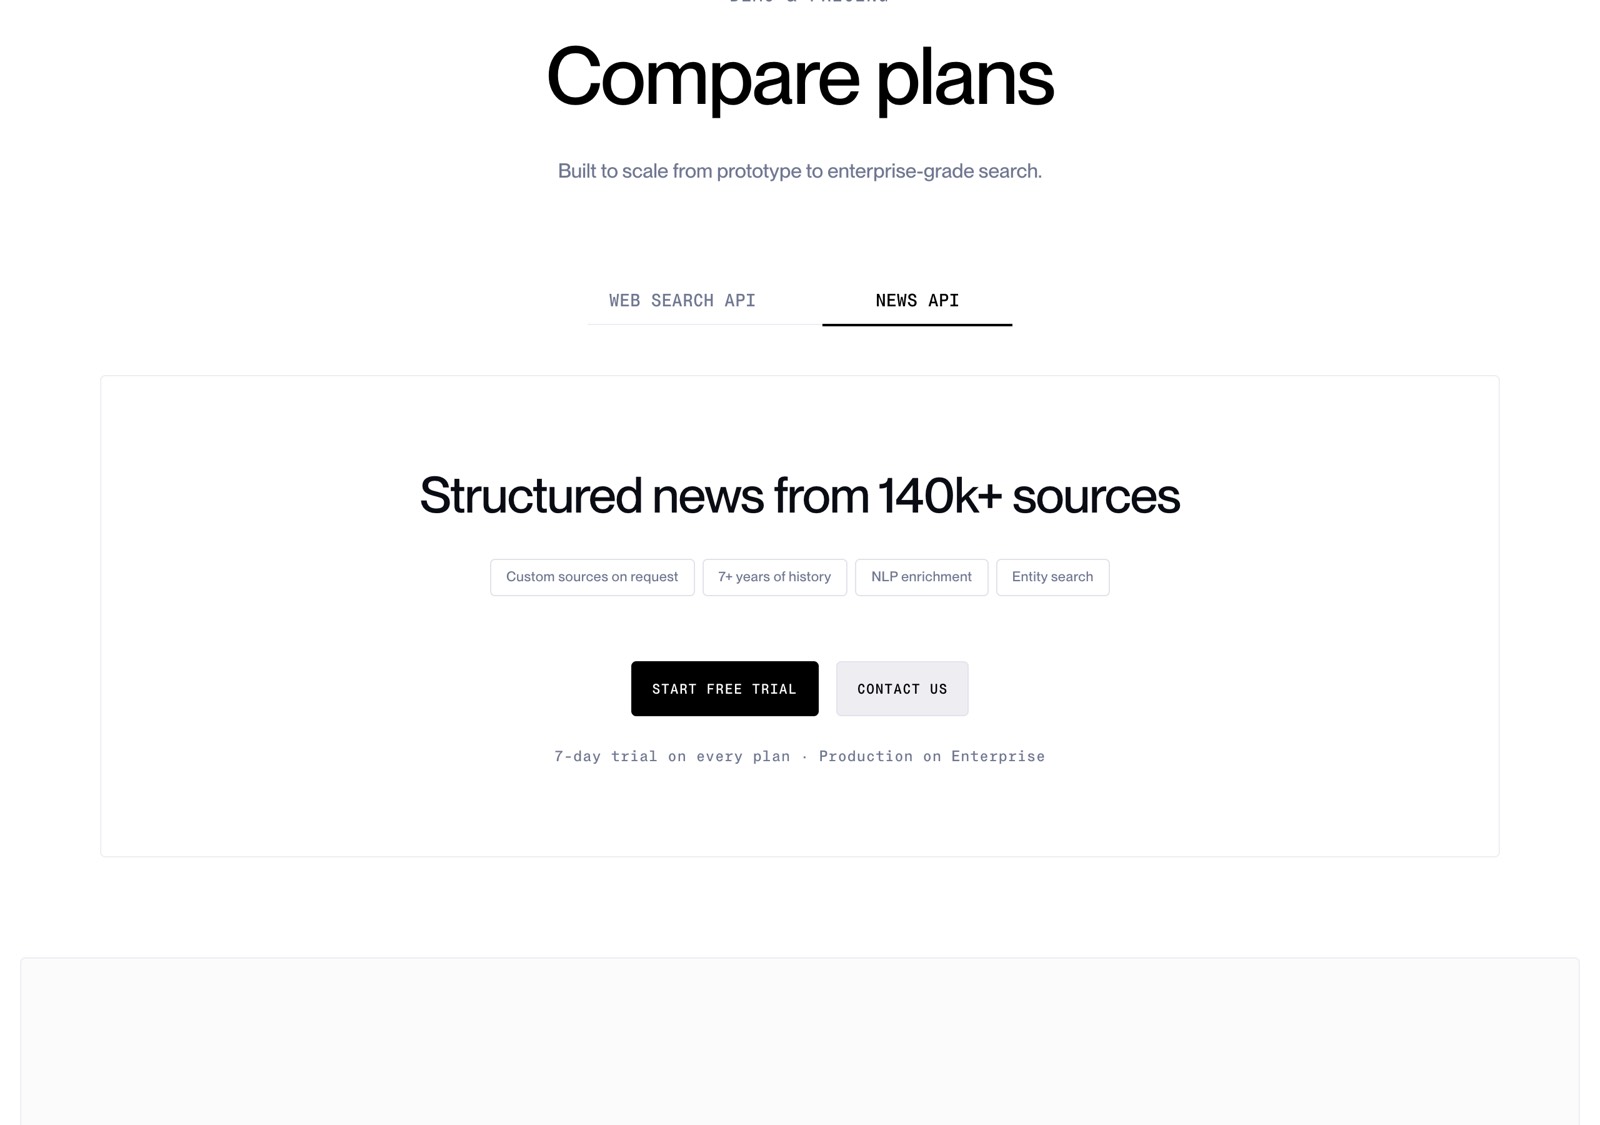
We re-read the Newscatcher page on 2026-11-02 and its text matches the capture. It shows no price, only "Start free trial" and "Contact us". Its "7+ years", "NLP enrichment" and "entity search" tags describe the Enterprise and archive product, not the self-serve plan we measured: the docs list the archive and named entities as Enterprise features. Our key was on a platform_free plan with a 10,000-credit balance.
Side by side
NewsData.io and Newscatcher cells are pages read and runs made on 2026-11-02 (Newscatcher's also from its /subscription endpoint). Feedmarkdown cells come from pages read and a run on 2026-11-01. Google News RSS is free, returns news.google.com redirect links and has no article text; its newest item was 4.0 h old for A and 4.2 h for B.
| NewsData.io | Newscatcher News API | Feedmarkdown | |
|---|---|---|---|
| Price | Free, then $199.99, $349.99, $1,299.99 a month | Credits: 1, 5 or 10 per search. No dollar price on the News API tab | $19, $49, $149 a month |
| History | 48 hours free; 6 months, 2 years, 10 years by tier | 30 days free; archive from 2019 is Enterprise | 7 days (Starter), 30 days (Pro) |
| Delay | 12 hours on Free; real-time on paid. Newest item 13.6 h (A), 12.2 h (B) | Newest item 1.1 h old (A), 6.4 h (B) | Check every 6 hours, hourly, or every 15 minutes by plan |
| Full text | Placeholder on Free | None: title, snippet, short summary | Markdown per article |
| Extras | AI tags, sentiment on all plans | Entities, sentiment, themes are Enterprise | None |
| Duplicates | removeduplicate parameter, duplicate flag |
Results grouped into stories; copies of one article are one result | Dedup before and after scraping |
| Rate limits | 1,800 credits per 15 min on paid plans | 1 request per second, no daily limit | Not published |
| Delivery | REST, streaming | REST | Signed webhook, or JSON Feed or Atom |
Sources: newsdata.io/pricing and documentation, newscatcherapi.com/pricing, and Newscatcher's current docs (credits, rate limits, effort levels, stories, enterprise plans), read 2026-11-02, plus GET /subscription on our key.
Terms, read 2026-11-02: NewsData.io says users may use the data for "personal or professional purposes" and may share or resell it at their own risk (newsdata.io/terms). Newscatcher's terms (last updated May 9th, 2025) restrict use for "commercial, or service bureau purposes or otherwise for the benefit of a third party", and its docs say redistribution rights come with a signed Enterprise agreement (newscatcherapi.com/terms-of-service section 1.3 and its enterprise-plans docs). Read both before reselling; this is not legal advice.
What we ran
Same two queries everywhere: A = solid-state battery, B = EU AI Act, English, US. Google News RSS, NewsData.io and Newscatcher (limit=50) ran between 17:35:52 and 17:41:58 UTC on 2026-11-02, 17 calls in all. Feedmarkdown ran on 2026-11-01 between 22:56 and 23:03 UTC. We tried to re-run it on 2026-11-02, but our test account had no active subscription that day (the API returned 402 subscription_required), so we kept the 2026-11-01 run. "Full text" means the article body in the response. "Same-story duplicate" means two items about the same event, whatever the outlet or headline; we counted by hand.
NewsData.io
Ten requests on a free key: 8 succeeded and 2 were refused with a 403. latest returned totalResults 26 for A and 37 for B, 10 per page. On 2026-11-01 it was 12 and 31.
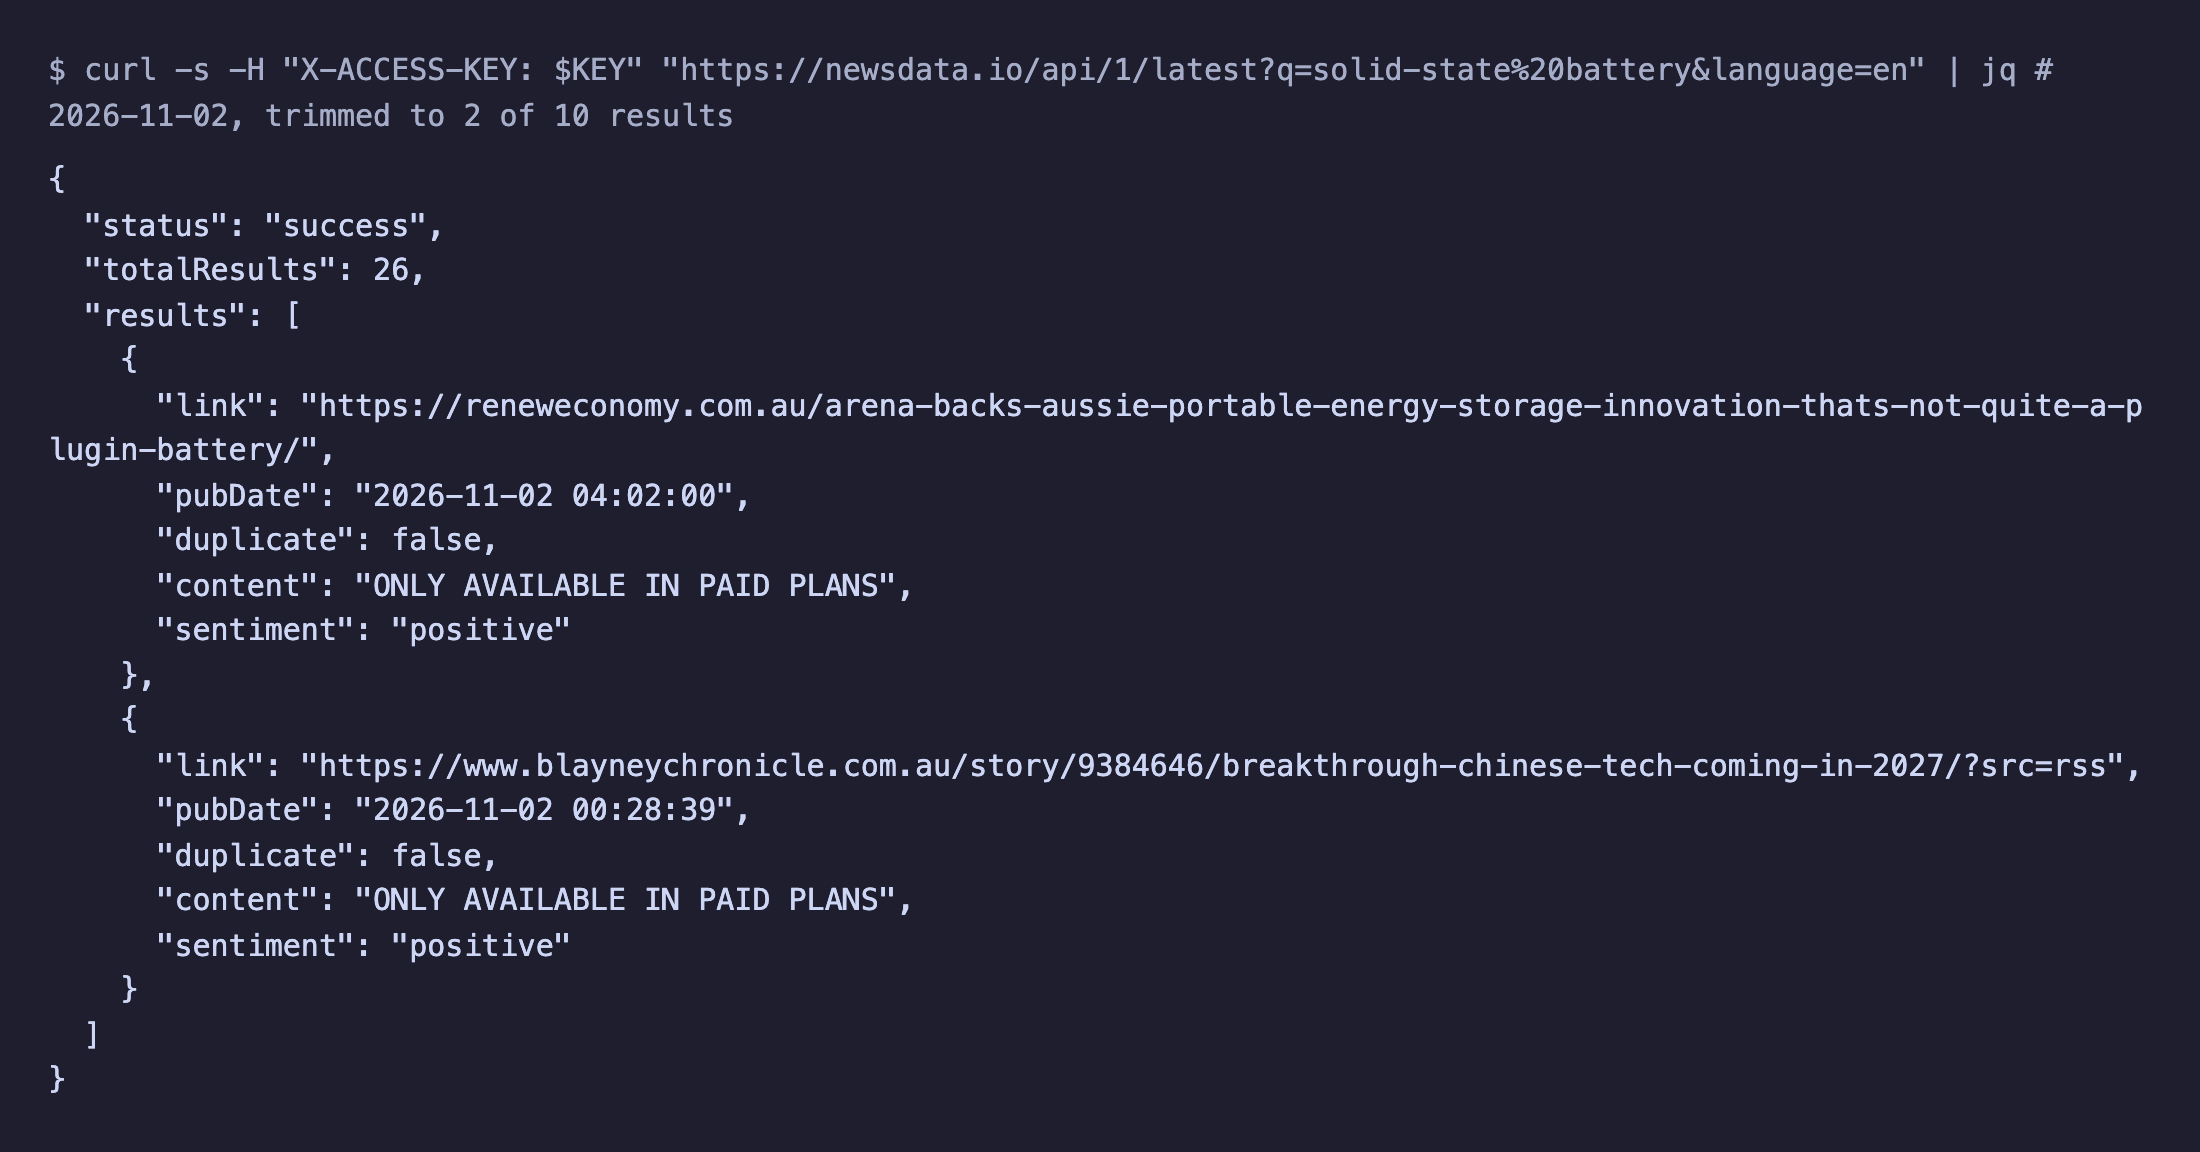
contentheld the placeholderONLY AVAILABLE IN PAID PLANSon every item returned. Full text on paid plans is untested.full_content=1and the archive endpoint returned 403.- Every link was a publisher URL. Results mixed in stock-ticker pages and off-topic stories, such as an Xbox controller piece and a takeout-order piece for A.
qInTitlereturned 0 results for both multi-word queries and 109 for the single wordbattery.- One credit per successful call. The two zero-result calls cost a credit too, although the pricing FAQ says empty results do not. Headers showed
X-RateLimit-Limit: 60; the docs give no free-plan number. - Newest item for A was 13.6 h old, B 12.2 h, which fits the 12-hour delay on Free (12 h 41 min and 12 h 38 min yesterday). Repeating A 18 seconds later returned the same 10 IDs.
removeduplicate=1cut B'stotalResultsfrom 37 to 29; the 10 items shown did not change.
Newscatcher News API
GET /subscription reported plan platform_free: up to 50 articles per page, 30 days of history, 1 request per second per effort level (and 1 shared), no daily limit, 1, 5 and 10 credits per low, medium and high search, story pages at 1 credit, no Enterprise fields, and a balance of 10,000 credits at 16:54 UTC. Searches cover the last 7 days unless you widen the window.
We ran five searches at about 16:55 UTC (A at low and medium, B at low, A at low with collapse=duplicates) and a repeat of A at low at 17:04 UTC. The balance fell from 10,000 to 9,990. At 17:36 UTC we ran A and B at low again in the shared window, and the balance went to 9,988. All HTTP 200. The numbers below are from the 17:36 run unless marked earlier.
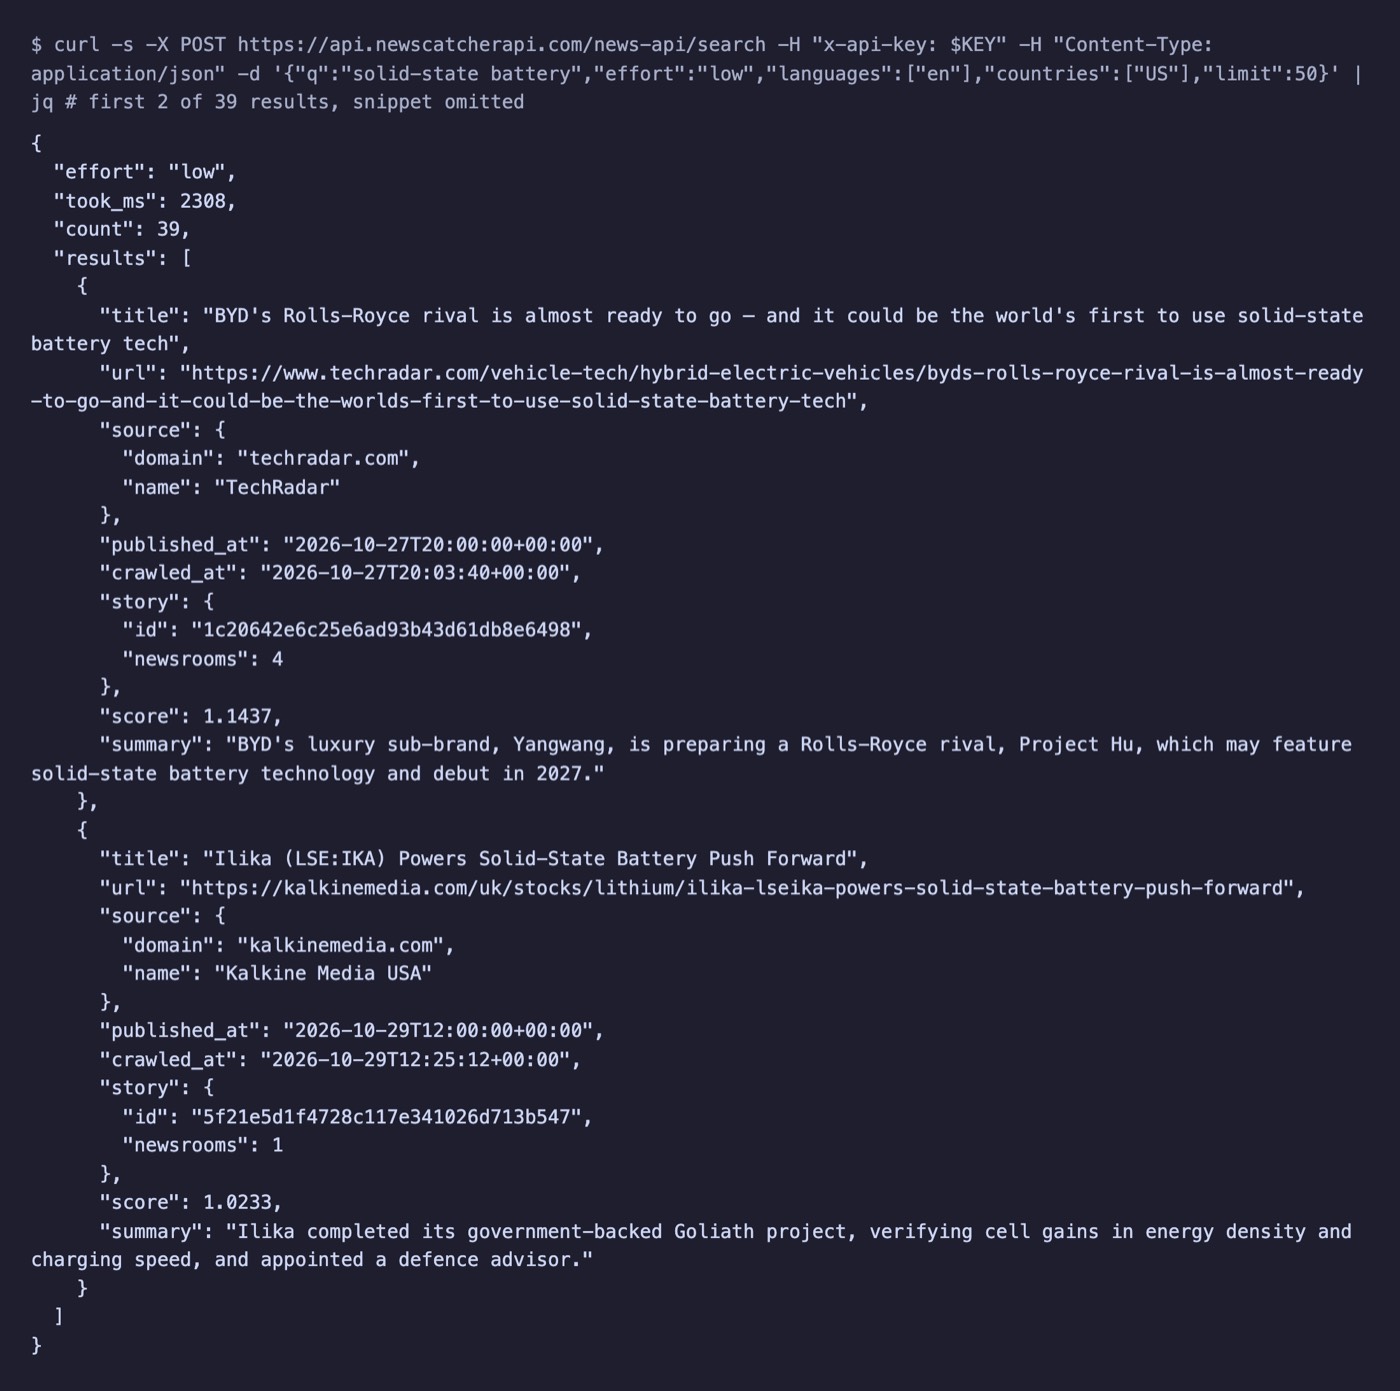
- Results. A returned 39 items in 2.3 s (server-reported) and B 35 in 2.2 s. Earlier, B returned 40. Every URL was a direct publisher URL.
- Fields. Title, snippet (up to 201 characters), summary (up to 187), source,
published_at,crawled_at, country, language,content_type,scoreandstory. No full-text field: no item had a body. - Freshness. The newest item was 1.1 h old for A and 6.4 h for B (1 h 49 min and 1 h 42 min earlier), so fresh is not guaranteed per query.
- Stories. The 39 items for A fell into 26 stories, 9 with more than one item. The biggest had 6 items about Svolt's 100-kWh batteries from six outlets, including aggregators such as newsbreak.com and wn.com. B had 35 items in 29 stories, 3 of them multi-item. Two of A's titles each appeared twice. We did not hand-check today's data for same-event pairs left ungrouped.
- Earlier-run checks.
mediumreturned the same 38 ids aslowin a different order: 5 of the top 10 matched, in 8.5 s against 3.4 s, for 5 credits against 1.collapse=duplicatesand a repeat 8.5 minutes later returned the same ids as the default. - Relevance. 14 of 39 items for A had no "solid" in title, snippet or summary, and 23 of 35 for B had no "AI Act" (28 of 40 earlier). Crude check: summaries are short.
What we did not test
Newscatcher: only the self-serve News API on platform_free. Not CatchAll, the Agent, any Enterprise feature (entities, sentiment, themes, translations, the 2019 archive, higher limits), effort=high, story pages, paid plans, or filters beyond language and country. Freshness and relevance are two snapshots. NewsData.io paid plans are untested too.
Google News RSS and Feedmarkdown
Google News RSS returned 100 items for A and 46 for B, with redirect links and a publisher name only. Repeating A 366 seconds later returned the same 100 items in a different order. On 2026-11-01 the repeat shared only 52 of 100 titles, so how much the tail moves varies.
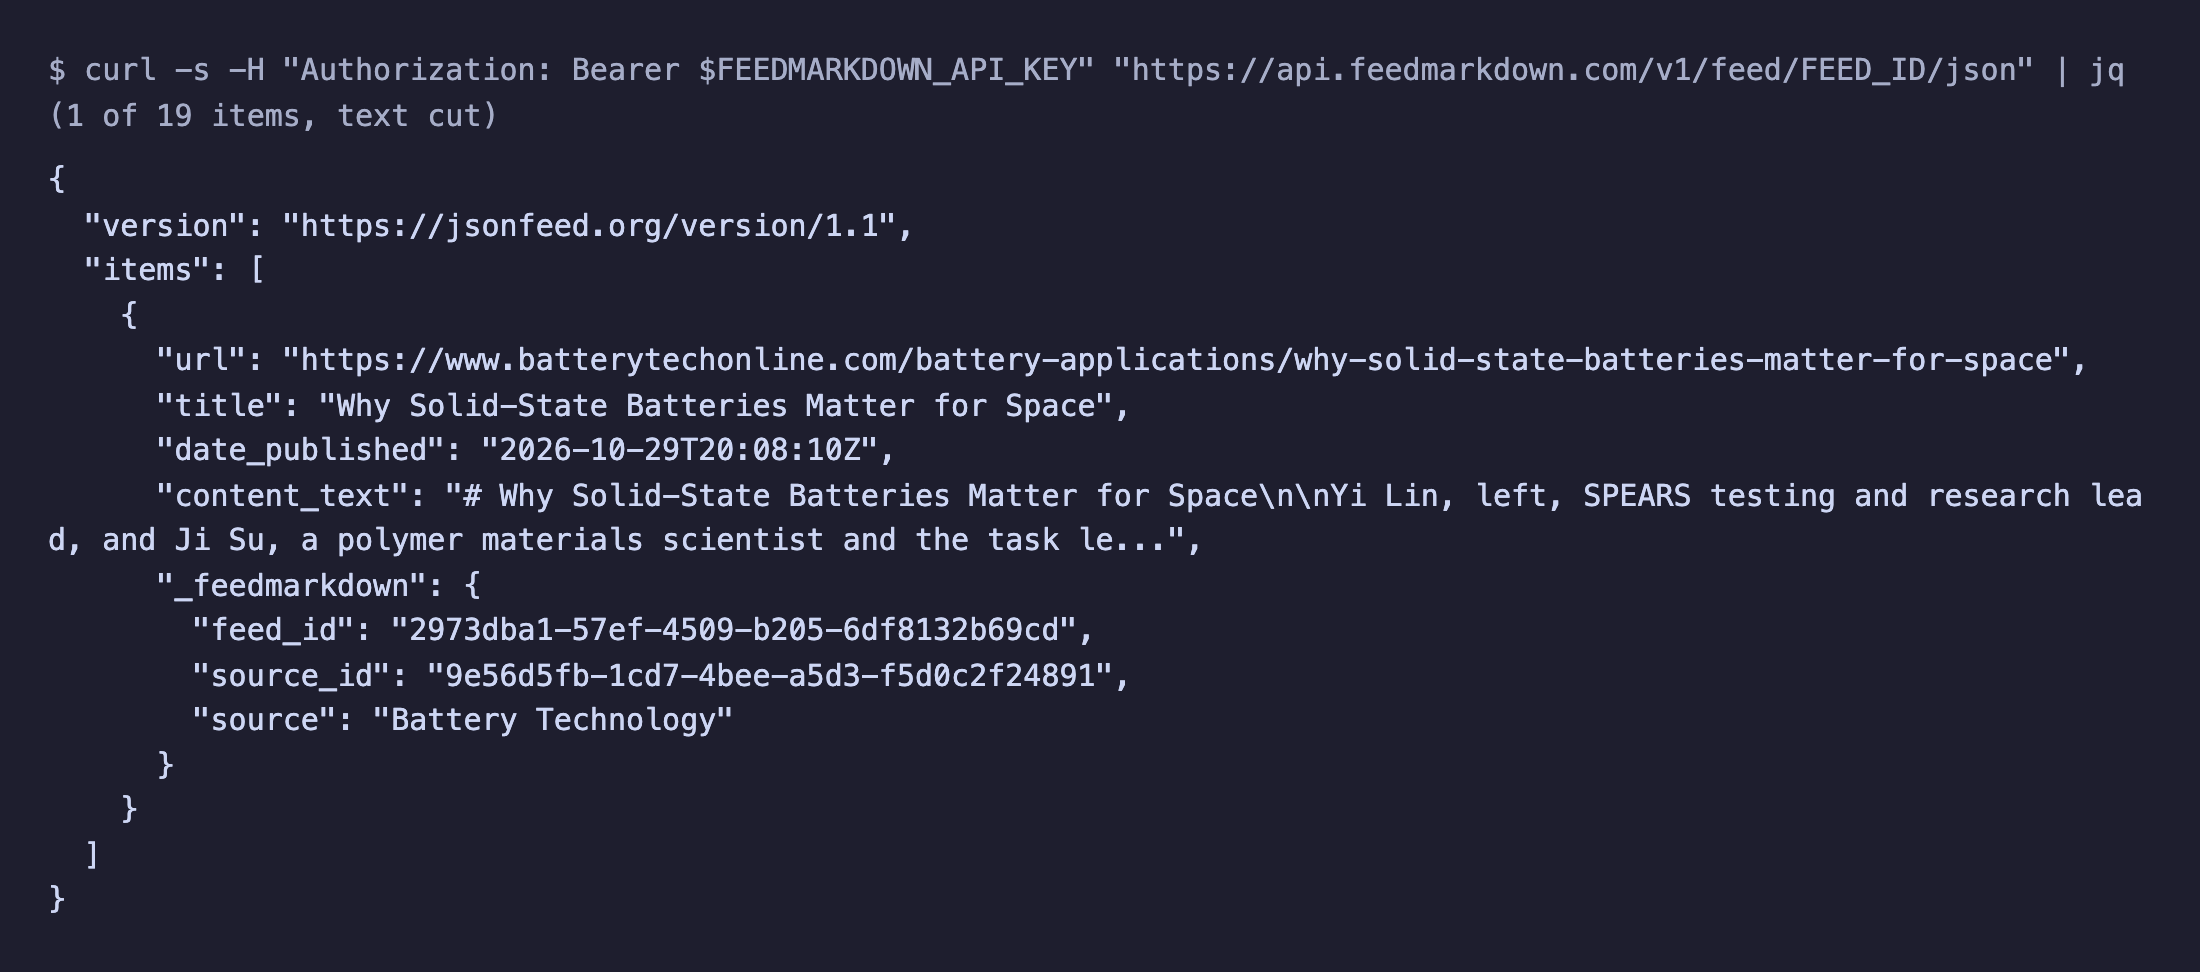
For Feedmarkdown (run on 2026-11-01) we created one feed with one google_news source for A (pull delivery, 20 items per run), let the first scheduled run start, read the JSON Feed, then deleted the feed and source. The run found 20 items, kept 19 as new, flagged 1 as a duplicate, scraped 19 and had 0 errors. It took 42 seconds. All 19 items carried Markdown, from 1,229 to 57,224 characters. One first run says nothing about the plan's check interval.
Overlap and duplicates
We matched each tool's items against Google News RSS items by headline similarity (shared words, 0.5 threshold), because RSS links are redirects. The RSS, NewsData.io and Newscatcher rows are from 2026-11-02, matched against that day's RSS fetch (the earlier Newscatcher run gave the same 7 of 38 and 2 of 40). Feedmarkdown's row is from 2026-11-01 and was matched against that day's RSS fetch. Full text: 0 items for every API row, 19 of 19 for Feedmarkdown.
| Tool and query | Items | Also in the RSS list | Same-story extras we found; flagged by the tool |
|---|---|---|---|
| Google News RSS, A | 100 | n/a | Not re-counted today |
| NewsData.io, A | 10 | 0 of 10 | 1 pair; 3 flagged (1 confirmed) |
| NewsData.io, B | 10 | 0 of 10 | Not counted; 0 flagged |
Newscatcher, A (low) |
39 | 7 of 39 | Not hand-counted; 26 stories, 2 titles repeated |
Newscatcher, B (low) |
35 | 2 of 35 | Not counted; 29 stories |
| Feedmarkdown, A (2026-11-01) | 19 | 19 of 19 (8 in RSS top 20) | 4; 1 |
The Feedmarkdown row is not clean. It dropped one duplicate, but 4 same-story items remain. Two stories came through three times each (an XPeng robot battery story and CATL's 20 Ah samples, each from three outlets), and headline clustering did not merge them. On 2026-11-01 NewsData.io flagged the one real pair we found in B plus two we could not confirm. Today its flags were on A: a repeated "Lithium Stocks To Research" item (a real pair) and two we could not confirm.
Low overlap with Google News on two queries says nothing about quality. Each API has its own index.
What it costs per 1,000 articles
NewsData.io price per credit is monthly price divided by credits, and articles per credit runs from 1 to 50 on paid plans (the page does not define its asterisk). We saw 10 articles per credit on Free and did not test a paid plan.
| NewsData.io plan | Price per credit | Per 1,000 articles at 1 per credit | At 50 per credit |
|---|---|---|---|
| Basic ($199.99, 20,000 credits) | $0.0100 | $10.00 | $0.20 |
| Professional ($349.99, 50,000) | $0.0070 | $7.00 | $0.14 |
| Corporate ($1,299.99, 1,000,000) | $0.0013 | $1.30 | $0.026 |
Free is $0 but delayed 12 hours and capped at 200 credits a day.
Newscatcher charges in credits per successful search (an empty search still counts; refused or failed requests do not): 1,000 searches cost 1,000 credits at low, 5,000 at medium and 10,000 at high. Our key showed a balance of 10,000 credits; no public page we read says whether that is monthly. The News API tab shows no dollar price per credit, so we give no price per 1,000 articles.
Feedmarkdown, from the pricing page: Starter $19 for 3,000 articles is $6.33 per 1,000; Pro $49 for 12,000 is $4.08; Agency $149 for 40,000 is $3.73. These are different units. A NewsData.io article may be a duplicate or off-topic and has no body on the tiers we saw. A Newscatcher item has a short summary but no body. A Feedmarkdown article is new, deduplicated and has full text. For the layers around a self-built pipeline, see what a newsletter's news stack costs per month.
Where each vendor is the better pick
- Newscatcher is better at direct publisher URLs, ranking by relevance, authority and freshness, story grouping, freshness on the free plan (newest item 1.1 h and 6.4 h old, against 13.6 h and 12.2 h on NewsData.io's free key), and a free plan that starts with 10,000 credits and searches the last 30 days.
- Newscatcher is weaker for this use because the self-serve plan has no full text, and relevance was noisy in our crude check.
- NewsData.io is better for long history by tier (6 months to 10 years) and for AI tags and sentiment on every plan.
- Sources beyond Google. Feedmarkdown reads Google News and Google Alerts only. If you need wider crawl coverage, use an API with its own index.
Building it from Google News RSS
The DIY chain has five steps. Fetch the feed (feed guide). Resolve the redirect links to publisher URLs (redirects). Scrape the articles (rate limits and what breaks). Remove duplicates (why headline matching is not enough, and duplicate stories in Google News). Deliver the result, for example with RSS to webhook. Keeping that running is what a news API sells.
When to pick which
| You need | Pick |
|---|---|
| Years of history | NewsData.io (6 months to 10 years by tier); Newscatcher only on Enterprise |
| Filters by language, country, publisher | Either API (we tested only language and country on Newscatcher) |
| Sentiment or tags | NewsData.io; Newscatcher only on Enterprise |
| Fresher headlines with direct URLs on a free plan | Newscatcher (1.1 h and 6.4 h for our two queries) |
| Full article text per item | Feedmarkdown, or a pipeline you build |
| What Google News ranks | Google News RSS or Feedmarkdown |
| Sources outside Google News | A news API (Feedmarkdown does not have them yet) |
Skip the plumbing
Feedmarkdown is the hosted version of the pipeline above. It reads Google News and Google Alerts, resolves redirects to publisher URLs, drops duplicates before scraping and again after, and returns each article as full-text Markdown by HMAC-signed webhook or as JSON Feed 1.1 or Atom you pull. Plan prices are in the pricing section. A subscription is needed to create or run feeds, and a 7-day trial starts from the billing page. If that fits, start a feed in the dashboard.