googlenewsdecoder ImportError: Modest backend is deprecated (Fix)
If from googlenewsdecoder import gnewsdecoder fails with ImportError: Modest backend is deprecated since selectolax 1.0, the cause is a dependency, not your code. selectolax 1.0 (released 2026-10-03) removed the parser that googlenewsdecoder 0.2.1 and older import. Pick one fix:
- Python 3.11 or newer:
pip install -U googlenewsdecoderinstalls 0.2.2, which is what we would do. Before you upgrade, note that 0.1.7 returns{"status": True, ...}while 0.2.x returns{"success": True, ...}, so code readingresult["status"]breaks silently. 0.2.2 can also fail to decode from some connections (see below). - Python 3.9 or 3.10, or if you want to keep your version:
pip install "selectolax<1.0". On those versionspip install -U googlenewsdecoderdoes not help. 0.2.x needs Python 3.11, so pip stays on 0.1.7, which still pulls selectolax 1.0.x.
This is what you see, from selectolax 1.0.2:
  File ".../site-packages/googlenewsdecoder/_parse.py", line 5, in <module>
    from selectolax.parser import HTMLParser
  File ".../site-packages/selectolax/parser.py", line 13, in <module>
    raise ImportError(DEPRECATION_MESSAGE)
ImportError: Modest backend is deprecated since selectolax 1.0. The engine has not been updated since 2021, while lexbor has been available since 2021 and is actively developed. [...] Please use lexbor backend instead: `from selectolax.lexbor import LexborHTMLParser`.
1.0.0 and 1.0.1 word the second sentence differently (see issue #20); the first sentence is the same.
We tested all of this on 2026-11-05 with googlenewsdecoder 0.1.7, 0.2.1 and 0.2.2, selectolax 0.4.13 and 1.0.2, and Python 3.9 to 3.13. For the full Google News RSS setup, see our Google News RSS feed guide. For what the decode call does, see the redirect post.
If you only need publisher URLs and article text, Feedmarkdown's Google News source resolves the links for you, so there is no decoder in your code.
Check your versions
python --version
pip show googlenewsdecoder selectolax | grep -E "^(Name|Version)"
If selectolax shows 1.0.0 or higher and googlenewsdecoder shows 0.2.1 or lower, you have this problem.
Fix 1: pin selectolax below 1.0 (any Python)
pip install "selectolax<1.0"
It resolved to 0.4.13 and the import works again. pip printed no conflict warning, even with googlenewsdecoder already installed.
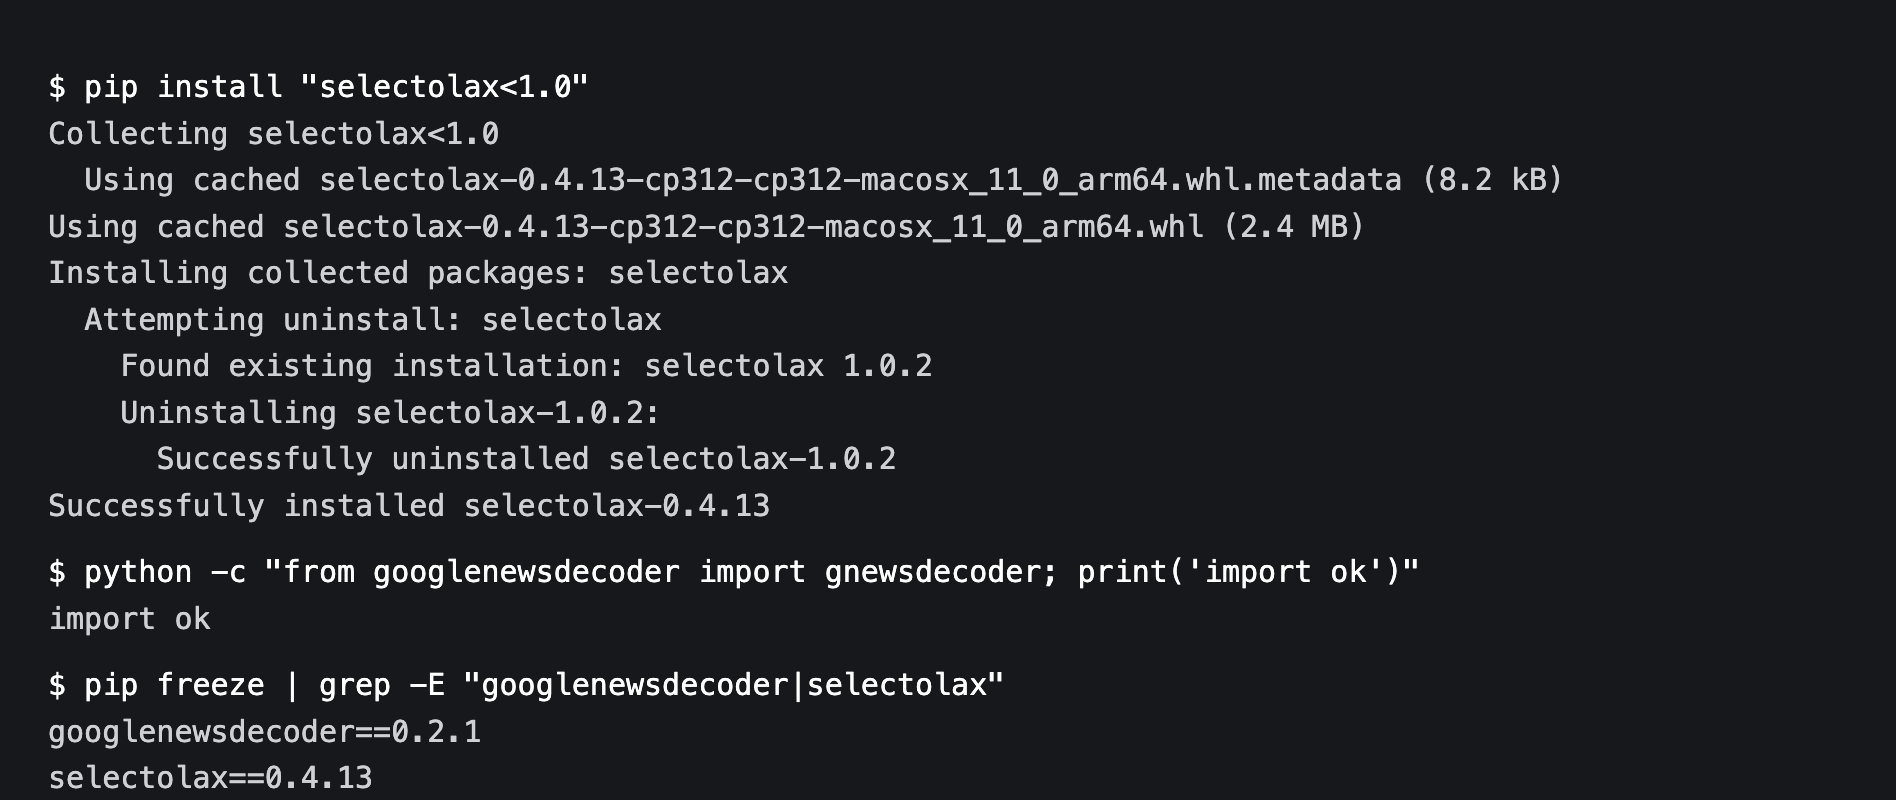
For CI and Docker, put the pin where the install happens. We ran these two forms:
# requirements.txt
googlenewsdecoder
selectolax<1.0
# constraints.txt contains: selectolax<1.0
pip install -c constraints.txt googlenewsdecoder
Both installed googlenewsdecoder 0.2.2 with selectolax 0.4.13 on Python 3.12, and the import worked. In a Dockerfile, use the same command in a RUN line. We did not test Docker, poetry, uv or pyproject.toml.
It is a stopgap. The selectolax maintainers call the old backend unmaintained since 2021, and 0.4.13 is the last 0.x release on PyPI.
Fix 2: upgrade googlenewsdecoder (Python 3.11+)
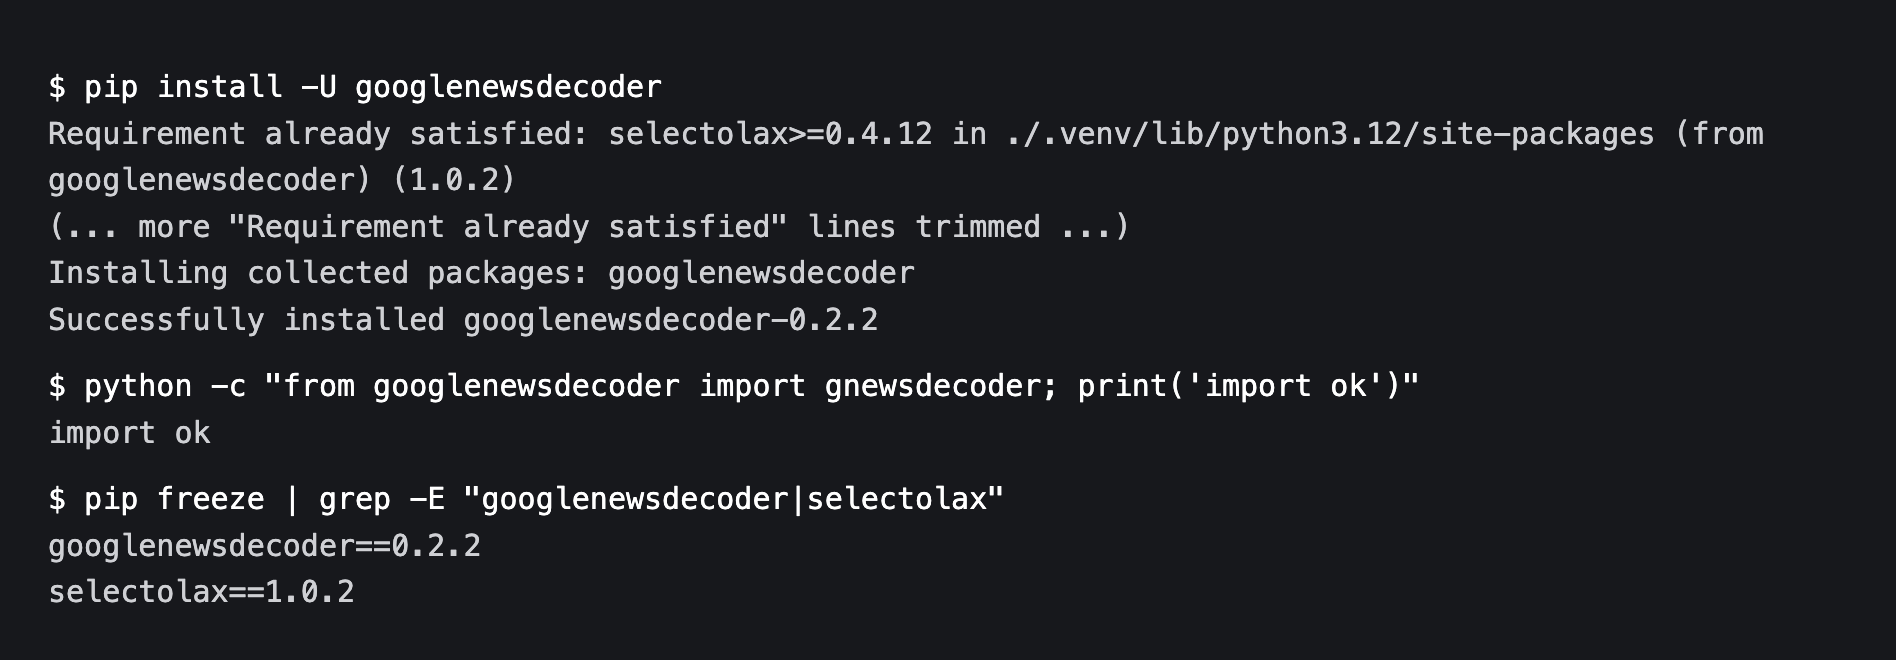
pip install -U googlenewsdecoder
On Python 3.12 this moved 0.2.1 to 0.2.2 and left selectolax at 1.0.2. A fresh install also imported cleanly on 3.11.2 and 3.13.1.
On Python 3.10 we recorded what pip does (trimmed):
$ pip install -U googlenewsdecoder     # installs googlenewsdecoder 0.1.7, selectolax 1.0.2
$ pip install googlenewsdecoder==0.2.2
ERROR: Ignored the following versions that require a different python version: 0.2.1 Requires-Python >=3.11; 0.2.2 Requires-Python >=3.11; 1.0.0 Requires-Python >=3.11
ERROR: No matching distribution found for googlenewsdecoder==0.2.2
The import still failed after the -U, and pip install "selectolax<1.0" fixed it. On Python 3.9 a plain install gave the same result. A yanked googlenewsdecoder 1.0.0 also exists on PyPI; pip skipped it in our installs.
Fix 3: patch the import to lexbor yourself
Do this only for a vendored copy or a fork. PR #21 (merge commit 2825651) is a three-line change to googlenewsdecoder/_parse.py:
--- a/googlenewsdecoder/_parse.py
+++ b/googlenewsdecoder/_parse.py
@@ -5 +5,2 @@
-from selectolax.parser import HTMLParser
+from selectolax.lexbor import LexborHTMLParser
+
@@ -90 +91 @@
-    node = HTMLParser(html).css_first("c-wiz > div[jscontroller]")
+    node = LexborHTMLParser(html).css_first("c-wiz > div[jscontroller]")
We applied it to a scratch copy of 0.2.1 with selectolax 1.0.2. The import worked and one decode returned a publisher URL. The css_first and attributes calls worked unchanged on the Lexbor parser. The maintainer's reply on issue #20 says the fix landed on main, and it shipped as 0.2.2.
googlenewsdecoder not working after the fix?
If the import works but the decode returns Failed to fetch data attributes from Google News, Google may be sending you to consent.google.com. It happened to us once, on 0.2.2, from a home connection. We did not test a datacenter or a US connection.
One run per setup on 2026-11-05, no cookies, a few seconds apart, no retries:
from googlenewsdecoder import gnewsdecoder

print(gnewsdecoder("https://news.google.com/rss/articles/CBMi...", interval=1))
| Setup (Python 3.12) | Result |
|---|---|
| 0.1.7 + selectolax 0.4.13 | {'status': True, 'decoded_url': ...} (an openai.com URL) |
| 0.2.2 + selectolax 1.0.2 | {'success': False, 'message': 'Failed to fetch data attributes from Google News.'} |
Google answered 0.2.2's request with a 302 to consent.google.com. The 0.2.x code only follows redirects that stay on news.google.com, so it gives up; 0.1.7 uses requests, which follows them. Setting the consent cookies on the client fixed it:
from googlenewsdecoder import GoogleDecoder

url = "https://news.google.com/rss/articles/CBMi..."
with GoogleDecoder() as d:
    d.client.cookies.set("CONSENT", "YES+cb", domain=".google.com")
    d.client.cookies.set("SOCS", "CAI", domain=".google.com")
    print(d.decode_google_news_url(url))
With the cookies set, 0.2.2, 0.2.1 with the pin, and 0.2.1 patched per PR #21 all decoded a link to its publisher URL (openai.com, cnbc.com, mashable.com). The redirect post did not need the cookies from its connection, so it depends on where you call from. In total we made 5 decodes and 1 redirect probe against Google, plus one RSS fetch.
What changed in selectolax 1.0
From the 1.0.0 release notes:
- The Modest backend is removed.
selectolax.parseris now a stub that raisesImportErroron import. - The replacement is
from selectolax.lexbor import LexborHTMLParser. The notes say Lexbor has been supported since 2021. parse_fragment()is removed. UseLexborHTMLParser(html, is_fragment=True).- Several fragment fixes are marked as breaking, and
attributesnow reports qualified attribute names.
If your own code has from selectolax.parser import HTMLParser, the migration is the same swap. We only ran it for googlenewsdecoder's one css_first call.
Why it hit every fresh install
googlenewsdecoder declared selectolax with a lower bound and no upper bound. Any new environment resolved to selectolax 1.0.x from 2026-10-03, while existing environments kept working until a rebuild. The GitHub issue was opened on 2026-10-13.
| googlenewsdecoder | selectolax constraint | Python | Status | Uploaded |
|---|---|---|---|---|
| 0.1.7 | >=0.3.27 |
3.9+ | Breaks with selectolax 1.0 | 2025-01-18 |
| 0.2.1 | >=0.4.12 |
3.11+ | Breaks with selectolax 1.0 | 2026-09-20 |
| 0.2.2 | >=0.4.12 |
3.11+ | Works with 0.4.13 and 1.0.2 | 2026-10-18 |
0.2.2 still has no upper bound, which is fine while Lexbor is stable. A future selectolax major release could break it again.
Why Google News decoders keep breaking
Every decoder depends on things Google can change. Each is covered in other posts, so briefly:
- The article id no longer carries the URL, so a decoder must ask Google (redirect post).
- That ask is an undocumented
batchexecutecall, which can change without notice. - Decoding in bulk can hit rate limits (scraping post).
- The answer depends on where you call from. We got the consent redirect above, and a public issue on cerulean-news measured a Cloudflare Worker getting HTTP 503 from
news.google.comwhile a laptop got 200.
Pin your dependencies and run a daily check that decodes one known link.
Alternatives to maintaining a decoder
For a one-off script, Fix 1 or Fix 2 is the right answer. Otherwise, the redirect post covers WebCrawlerAPI's Go and JavaScript resolvers and a standard-library resolver with no selectolax. We know of no official public Google News API; see Is there a Google News API.
Or skip the decoder. Feedmarkdown's Google News source resolves news.google.com links to publisher URLs before dedup and scraping, so you maintain nothing. It delivers full-text Markdown by HMAC-signed webhook, or JSON Feed 1.1 or Atom to pull, and it is paid only with a 7-day trial; see the pricing.